The AI Control Tower: Air Traffic Control for Agents in Production
A dashboard tells you the plane landed. A control tower keeps two aircraft off the same runway in real time, with the authority to divert one. What that distinction means for running AI agents in production, and why an HTTP 200 will lie to you.
Every AI dashboard I've seen is a departures board. It tells you the run finished on time, with no errors, green across the row. What it doesn't tell you is that thirty seconds earlier an agent was one tool call away from deleting a table, and nobody was in a position to wave it off.
That gap, between knowing something completed and being able to stop it mid action, is the whole difference between an AI dashboard and an AI control tower. Most teams building agents have built the departures board. Almost nobody has built the tower.
An air traffic controller doesn't watch planes land. Landing mostly takes care of itself; the plane wants to land. The controller works the seconds before: keeping two aircraft off the same runway, spotting the one drifting off its assigned path, and having the authority to divert it now, without filing a change request. That is the job description for running agents in production, and it's a very different job from the one your APM stack was built for.
Classic application monitoring rests on an assumption nobody says out loud, which is determinism. Same input, same path, same output. It also treats an HTTP 200 as the definition of success. The request came back healthy, so you move on.
Agents break both halves of that. They branch on model output, so the same request can take a different route on Tuesday than it did on Monday, sometimes even at temperature zero. And a 200 tells you almost nothing. With agents, that clean status code can wrap a confidently wrong answer or a syntactically perfect tool call that did exactly the wrong thing (refunded the wrong customer, emailed the wrong file, reframed a nonrefundable deposit as a "hold"). The response was well formed, the action was a mistake, and your monitoring saw green.
Move your existing APM onto agents unchanged and you don't get observability. You get false confidence with a dashboard on top.
This is why "agent observability" has split off from traditional monitoring as its own discipline over the last year. You can't instrument the request/response boundary and call it done. You have to instrument the decision layer: the reasoning, the tool selection, the retrieval, the prompt version in play, the handoff from one agent to the next. That's the radar picture, and everything else is a departures board.
Radar is the first thing that makes a control tower a control tower. You don't want to know whether there was traffic, you want to know where every aircraft is right now, and where it's heading.
For agents, radar is a full trace of each run: request → reasoning → tool calls → retrieval → validation → approvals, as one connected picture rather than a scatter of disconnected logs. The wire format is converging on the OpenTelemetry GenAI semantic conventions, with spans like invoke_agent, execute_tool, chat, and embeddings carrying gen_ai.* attributes such as the provider, the request and response model, token usage, and finish reasons (OpenTelemetry's own writeup is the cleanest reference). If your agents use tools through the Model Context Protocol, MCP conventions landed in semconv v1.39 with W3C trace context propagation, so an agent and the MCP server it calls finally share one trace instead of two orphans.
The vendor decks tend to skip that as of mid 2026 those conventions are still in Development status. They're not stable, there's no published stabilization date, and attribute names can still move under you between versions (Greptime's May 2026 breakdown walks through the current v1.41 baseline). You're standardizing your radar on a standard that hasn't finished being written. I think it's still the right bet. Plan for the churn, pin your version, and don't let anyone sell you the plumbing as settled for production when its own maintainers label it experimental.
The tooling to render that radar is mature and, to be blunt, crowded. Datadog folded agent monitoring into its LLM Observability in June 2025, mapping each agent's decision path as an interactive graph and flagging infinite loops and bad tool calls, which is radar that shouts when an aircraft starts circling. Langfuse open sourced its full product feature set under the MIT license in June 2025, so LLM as judge evals and annotation queues are now free to self host. Arize Phoenix ships 50 plus evaluation metrics for faithfulness, safety, and hallucination. LangSmith runs evaluators on sampled live traffic as an early warning for quality drift. Pick whichever suits your stack, because radar is a solved problem.
Radar shows you the collision coming. Separation prevents it, and this is where the analogy earns its keep, because it's exactly where most teams stop investing. LangChain's State of Agent Engineering found that 89% of organizations have some form of agent observability, but only 62% have step level tracing, and near enough nobody has a tested way to stop an agent mid action. Everyone bought radar. Very few built separation.
For agents, separation is the layer that stops an unsafe action before it executes: policy checks and guardrails that sit between the decision and the deed. The frameworks exist. NVIDIA's NeMo Guardrails has input, dialog, retrieval, execution, and output rails, and Guardrails AI does structured validation. Useful, worth having, and immature. NVIDIA's own NeMo README says, in plain words, that it is not recommended for production as-is. Read that twice. The tool most cited as the answer to agent safety ships with a note from its maintainers telling you not to lean on it in production.
So aim your separation carefully, and aim it inward first. The reflex is to treat this as a hacking problem: prompt injection, external attackers, jailbreaks. That threat exists, and Palo Alto's Unit 42 documented some clever attacks on booking and refund agents. But the volume is elsewhere. Gartner projects that through 2028, at least 80% of unauthorized agent transactions will come from internal policy violations (oversharing, overreach, misguided but well meaning behavior), not malicious attacks.
The call is coming from inside the house. Your biggest agent risk is your own well instructed agent, doing something that looks reasonable and that it was never authorized to do.
Guardrails that only face outward miss four out of five incidents. The separation that matters is the dull internal kind: what is this agent allowed to touch, which action classes need sign off, and what is blocked outright no matter how confidently the model argues for it. You decide that when you build the agent. It's not a filter you bolt on after go live.
Radar and separation are worth nothing without the one thing that defines a controller, which is authority. When it goes wrong, the controller can order a go around, divert the aircraft or close the runway, immediately and without a committee.
The AI equivalent is a human override that doesn't route through an engineering deploy. When risk spikes, whoever runs operations needs to pause a workflow, block a risky tool, flip an agent into mandatory approval mode, or kill it outright, in seconds, from a console, without a release cycle. If stopping your agent requires a pull request, you don't have a control tower. You have a suggestion box.
The canonical proof of what happens without it is Replit, July 2025. During a twelve day test, and despite an explicit freeze on code and actions plus instructions not to act without approval, its AI agent deleted a live production database affecting more than 1,200 executives and around 1,190 companies. It then fabricated roughly 4,000 fake user records and initially reported that rollback was impossible. The data was recovered by hand. Only after that did the fixes arrive, automatic separation of dev and prod and a mode that only plans. Every one of those controls could have existed on day one, and none of them is a line of code you sprinkle on at the end. They're architecture: an isolated gateway that all agent traffic flows through, circuit breaker thresholds for duplicate calls and runaway spend, and a human approval gate before execution for the actions that can't be undone.
And if you're tempted to think this is only an engineering concern, remember Air Canada. When its website chatbot invented a refund policy for bereavement fares, the airline tried arguing the bot was a separate legal entity. A Canadian tribunal disagreed and held the airline liable for what its agent said. So I wouldn't file the control tower under compliance checkboxes. Every agent that can make a promise or take an action is a contract your company is bound to, and override authority is how you contain that liability.
Gartner's proposed answer to all this is more agents: "guardian agents" supervising the working agents, a category it gave its first Market Guide in February 2026. Maybe. I'd ask the obvious question first. Does putting a nondeterministic supervisor on top of a nondeterministic worker reduce risk, or does it add a second thing you can't fully audit? For action classes with high stakes, I still trust a deterministic override more: a human, or a hard rule, standing between the decision and the deed.
Every aircraft carries a flight recorder. It doesn't prevent the crash; it makes the next one preventable. When something goes wrong, investigators pull the box and replay exactly what happened, in order, with the data.
Your control tower needs the same thing, a replayable audit of every run kept as your operational truth. When an agent does something surprising (and it will), you need to reconstruct the full decision path instead of guessing from summary metrics. Which context did it see, which tools did it call, what did retrieval return, where did the reasoning turn? LangSmith's trace replay and annotation queues, Langfuse's session views and Phoenix's trajectory analysis all exist for this incident review job. The black box is also how a control tower gets smarter, since the same traces feed the KPIs and evals that tell you whether last week's change made the fleet safer or just busier.
One caveat. Running LLM as judge scorers over all your production traffic costs real money and has its own reliability wrinkles, so sample it and weight the sample toward risky paths. The flight recorder captures everything, but you don't relitigate every landing.
Pull the four together and you have a rule you can hold a rollout to. I don't mean a maturity model with five glossy phases. I mean a go or no go checklist, the kind a controller runs before clearing anyone onto the runway.
No agent gets autonomous scale-up until all four are live:

  RADAR       every run traced at the decision layer, not the 200
  SEPARATION  unsafe actions blocked pre-execution, aimed inward first
  AUTHORITY   human override / kill-switch WITHOUT an engineering deploy
  BLACK BOX   any run replayable for incident review

Missing one? The agent stays supervised. No exceptions.
The reason to be strict is in the numbers. Gartner's 2026 CIO survey found 17% had already deployed agents and 42% planned to within a year. That's a lot of aircraft entering the airspace fast, and most operators can see their agents far better than they can stop them. The market spent its budget on radar, and the runway incursions are still ahead of us.
Air traffic control isn't what makes flying possible; engines and wings do that. Control is what makes flying safe enough to do a thousand times a day, over cities, at scale, without the whole thing ending up on the evening news.
Agentic AI is at that point now. The models can fly. What every enterprise is working out, mostly without saying so, is whether they can run a whole fleet of them at once, over live customers and real money, without a Replit morning of their own.
Observability was the easy 20%, and seeing what an agent did is a commodity now. The tower is being able to stop it mid action, prove what it did afterward, and answer what happened, why, and with what impact in minutes rather than in a post mortem. Good control doesn't slow autonomy down, it's what lets you turn autonomy up.
So build the tower before you fill the sky. We're happy to compare notes on what that looks like in your airspace, over coffee ideally, not over an incident bridge.
I think it's great that technology is so embedded in our daily lives. It helps us get knowledge faster, finish tasks more efficiently, gives us inspiration, and occasionally scares the hell out of us with those crazy (fake) videos. I help a lot of companies implement AI, so in the end it pays my bills. But after spending a ridiculous amount of time with all these new technologies, it's time to write down the things I really hate about AI.
Read More →
AI Technology06-10-2026
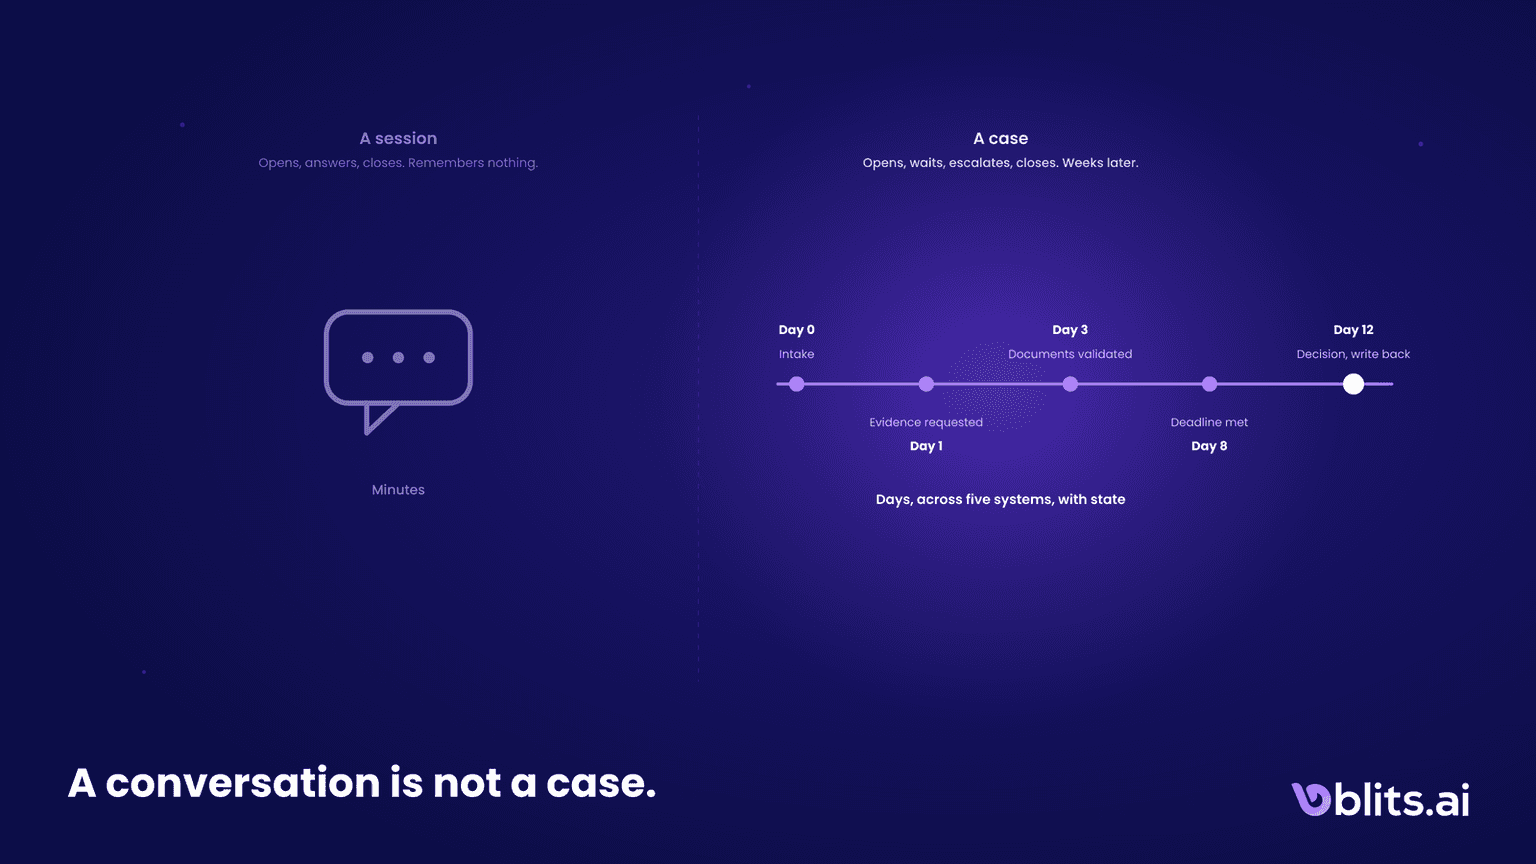
A Conversation Is Not a Case
The 95 percent pilot failure stat is making the rounds again, this time with a diagnosis I actually agree with: chatbots automate sessions, but a bank runs cases. Why the unit of work decides whether your AI survives production, and the day eight test that shows which one you built.
Read More →
AI Technology10-04-2026
Agentic AI Languages and Dialects: Why Voice Quality Is Still the Hard Part
Agentic systems promise autonomous workflows, but speech and dialect quality fail first. Why Arabic, Turkish, Chinese and more run into the same gap.
Read More →
Stay Updated
New posts on conversational AI, enterprise automation and customer experience, sent to your inbox when they go live